

Archive position — measured, not model output
0 likes on Devpost
2,263 of the 7,850 archived projects have more likes, and 5,587 share exactly 0 — so this project's #6,150 place in the like-ranked listing is a tie-break inside that group, not a ranking.
Projects (log scale)
Likes on Devpost. ▲ marks this project's group.
Show the figures
| Likes | Projects | Share of archive |
|---|---|---|
| 0 | 5,587 | 71.2% |
| 1 | 1,758 | 22.4% |
| 2 | 284 | 3.6% |
| 3–4 | 132 | 1.7% |
| 5–9 | 75 | 1.0% |
| 10+ | 14 | 0.2% |
 User Stories BotA demo video on every pull request
Get a demo video on every new feature
GitHub App that watches your pull requests and records a narrated, captioned demo.
Save time on demo prep and make informed decisions faster with a video walkthrough of every new feature.
Executive Summary
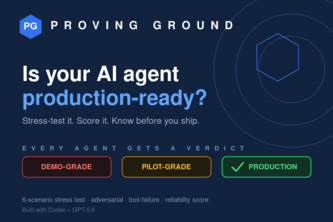
What the company appears to be: Proving Ground is a self-reported tool designed to evaluate AI agents for production readiness by running them through adversarial and failure scenarios. The author states it was built as a response to the lack of reliable testing infrastructure in the AI agent space, particularly around how agents behave under stress or error conditions.
What changed: The project description indicates a shift from general AI interest to a specific focus on reliability testing for AI agents. It emerged from personal experience and frustration with the gap between demo-grade performance and real-world production behavior.
Single most important open question: Is there evidence that Proving Ground has been used or validated by others beyond its creator, or whether it has moved beyond prototype status?
What The Product Actually Is
The description states that Proving Ground is a tool that stress-tests AI agents using a standardized battery of six scenarios:
- Happy path
- Ambiguous input
- Adversarial injection
- Tool failure
- Multi-step
- Out of scope
It evaluates these against a rubric with four criteria: task completion, honesty about failure, staying in scope, avoiding hallucination. The tool returns a reliability scorecard with one of three assessments: Demo-grade, Pilot-grade, or Production-grade.
The system can accept either:
- Pasted agent instructions and mock tools
- A live HTTP endpoint (deployed agent's API)
It uses a judge model to score transcripts, but includes deterministic guards for tool failure scenarios to prevent false positives.
Inference: The product is described as an evaluation harness that tests agents against defined failure modes, not a production agent itself.
Positioning & Claim Evolution
The author positions Proving Ground as a solution to the problem of unreliable AI agents in production — specifically citing that 88% of AI agents fail once they hit production. This claim is self-reported and unverified.
The product's positioning evolves from:
- A personal answer to a question ("how do you actually know if it works?")
- To a tool for validating agent reliability before shipping
- To infrastructure for new AI builders without prior AI experience
It frames itself as an objective, defensible way to assess whether agents are ready for production — not just impressive in demos.
Inference: The positioning is driven by the author's personal frustration with lack of testing tools and a desire to make agent development more rigorous.
Target Customer & ICP
The description states that Proving Ground targets:
- AI builders who are new to AI but want to validate their agents
- Anyone entering the AI agent space wondering if an agent is reliable enough to ship
- Developers or teams looking for objective signals of agent readiness
It also mentions a longer-term goal of helping people "validate an agent idea and build the confidence to ship it, backed by a real reliability signal rather than hype."
Inference: The ICP appears to be early-stage AI builders, especially those without deep AI backgrounds, who are uncertain about whether their agents will perform reliably in production.
Business Model & Pricing Evidence
No information is provided about pricing or business model. The description does not mention any monetization strategy, customer acquisition plans, or revenue streams.
Not evidenced
Technical & Delivery Signals
The project was built using:
- Codex
- GPT-5.6
- Next.js (App Router)
- TypeScript
- Tailwind
- OpenAI Agents SDK
Key technical decisions include:
- A deterministic regression guard on top of the model judge to prevent false successes in tool failure scenarios.
- SSRF-safe endpoint testing with URL validation to block private/internal addresses.
- Graceful degradation for bad configs, timeouts, rate limits, and provider errors.
The system captures full transcripts from target agents and scores them using a separate judge agent.
Inference: The technical stack suggests a modern web-based evaluation tool built on AI-as-a-service platforms, with attention to security and robustness in testing.
Traction & Maturity Signals
There is no evidence of traction or adoption beyond the author's own development. No customers, users, or usage data are mentioned. The project was submitted to a hackathon and described as a working prototype.
Not evidenced
Competitive Context
The description does not mention any competitors or existing solutions in this space. It frames Proving Ground as addressing a gap in the market — specifically around testing AI agents for reliability, especially in failure scenarios.
Not evidenced
Open Questions & Risks
- Unverified claims: The 88% failure rate is self-reported and unverified.
- No traction or validation: No evidence of use by others beyond the creator.
- Limited scope: Only one person on the team, suggesting limited capacity for scaling.
- Self-contained tool: No indication of integration with other platforms or ecosystems.
- Unproven business model: No mention of monetization or customer base.
Inference: The lack of external validation and traction raises questions about whether Proving Ground has reached a point where it can be considered a viable product or service.
Questions the description leaves open
- What specific evidence do you have that 88% of AI agents fail in production?
- Have you tested this tool on any real-world agents beyond your own?
- How are you planning to scale beyond one person building and testing?
- Is there a plan for monetization or customer acquisition?
- What is the current status of the product — is it live, in beta, or still under development?
Overall Assessment
The description indicates that Proving Ground is currently a prototype built by one person as part of a hackathon submission. There is no evidence of traction, revenue, customers, or a clear business model.
Not evidenced
User Stories BotA demo video on every pull request
Get a demo video on every new feature
GitHub App that watches your pull requests and records a narrated, captioned demo.
Save time on demo prep and make informed decisions faster with a video walkthrough of every new feature.
Source
Submitted to the OpenAI 2026 hackathon on Devpost. Project home on Devpost. Back to the full gallery on Devpost.
This competitive analysis was produced by top-founders.com (opens in a new tab)
Generated by a language model from this project's public Devpost page — its tagline, the author's own write-up and any built-with tags listed there — as captured in August 2026. Short quotations are the author's words. It is an opinion on the idea as a business, not on the people behind it, and it reflects the description as published then. If the project has moved on, request a correction below. The analysis is not independent research and contains no verified traction, revenue or customer data.
An independent guide by KFG International LLC — not affiliated with, endorsed by, or connected to Devpost or OpenAI.