

Archive position — measured, not model output
0 likes on Devpost
2,263 of the 7,850 archived projects have more likes, and 5,587 share exactly 0 — so this project's #4,689 place in the like-ranked listing is a tie-break inside that group, not a ranking.
Projects (log scale)
Likes on Devpost. ▲ marks this project's group.
Show the figures
| Likes | Projects | Share of archive |
|---|---|---|
| 0 | 5,587 | 71.2% |
| 1 | 1,758 | 22.4% |
| 2 | 284 | 3.6% |
| 3–4 | 132 | 1.7% |
| 5–9 | 75 | 1.0% |
| 10+ | 14 | 0.2% |
 User Stories BotA demo video on every pull request
Get a demo video on every new feature
GitHub App that watches your pull requests and records a narrated, captioned demo.
Save time on demo prep and make informed decisions faster with a video walkthrough of every new feature.
Executive Summary
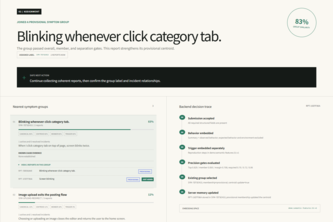
What the company appears to be: Issue Memory is a self-reported hackathon project that uses text embeddings to group fragmented bug reports into evolving symptom groups. The author describes it as an experiment in applying embedding technology beyond traditional search, focusing on relationships among stored elements rather than retrieval.
What changed: The project evolved from an initial brainstorming phase involving GPT-5.6 in Codex to a working prototype that implements a system for comparing new bug reports against existing ones using embeddings, with the goal of creating shared organizational memory around symptoms.
Single most important open question: Is there evidence of real-world traction or commercial viability beyond this single-person hackathon project? The description states no revenue, customers, or adoption data exist beyond the author's own account.
What The Product Actually Is
The description states Issue Memory is a system that uses text embeddings to turn fragmented bug reports into evolving symptom groups. It implements a model where:
- Original bug reports are stored
- Reports are compared using embedding similarity
- Similar reports are grouped into "symptom groups"
- Each original report retains its relationship to the symptom group
- The system distinguishes between:
- Report (the raw input)
- Symptom group (the embedded cluster)
- Incident (the specific occurrence)
- Root cause (the underlying issue)
The author describes this as a "create, compare, group, and update cycle" that works in temporary server memory without requiring an external database.
Positioning & Claim Evolution
The description states the project was built to explore how text embeddings could be applied beyond traditional search use cases. The author's positioning evolved from:
- Initial brainstorming about embedding applications
- Focusing on relationships among stored elements rather than simple retrieval
- Identifying a specific problem: distinguishing between symptoms and root causes
- Developing a system that separates reports from symptom groups from incidents from root causes
The claim is that embeddings can reveal insights hidden in fragmented bug reports, creating "organizational memory" around symptoms. The author positions this as an experiment in applying embedding technology to software development workflows.
Target Customer & ICP
Not evidenced. The description does not identify specific target customers or personas beyond the general context of software development teams dealing with bug reports.
Business Model & Pricing Evidence
Not evidenced. There is no information provided about pricing, monetization strategy, or business model in the self-reported description.
Technical & Delivery Signals
The description states Issue Memory was built using:
- Next.js
- OpenAI text embedding 3-small API
- TypeScript
- Vercel platform
Key technical elements include:
- Implementation of a system that compares new bug reports with existing embedded reports
- Use of embedding similarity for grouping
- Temporary server-side storage for reports, vectors, and memberships
- A structured data model that separates reports from symptom groups from incidents from causes
- Provider abstraction for mock and OpenAI embedding modes
The author describes GPT-5.6 in Codex as a collaborator throughout the development process, including:
- Exploring and narrowing the original idea
- Evaluating datasets
- Designing data structures
- Implementing backend logic
- Building user interface
- Diagnosing false positives and improving scoring
Traction & Maturity Signals
Not evidenced. The description makes no claims about revenue, customers, adoption, or usage metrics beyond the author's own account of building a hackathon project.
Competitive Context
Not evidenced. No information is provided about competitors, market positioning, or competitive landscape in the self-reported description.
Open Questions & Risks
- Single-person operation: The project was built by one person (Sanghun Kim) with no indication of team expansion or commercialization
- Hackathon context: Built for a hackathon with no evidence of post-hackathon development or traction
- No commercial evidence: No revenue, customers, or adoption data provided beyond the author's own account
- Limited scope: The system works in temporary server memory and has not been moved to durable storage
- Unverified claims: All statements are self-reported without independent verification
Questions the description leaves open
- What specific problems in software development workflows does this address that existing tools don't?
- How would you scale this beyond a single-person hackathon project?
- What is your plan for moving from temporary server memory to durable storage?
- Have you identified any real-world use cases or potential customers beyond the author's own experience?
- What are the technical limitations of the current approach that would need to be addressed for production use?
Overall Assessment
Not evidenced. The description provides no information about funding rounds, valuations, or investment status beyond the fact that it was submitted to a hackathon.
The author states this is a self-reported, unverified account of a hackathon project with no evidence of traction, revenue, customers, or adoption. All claims are based on the author's own description and have not been independently verified. The project appears to be a single-person experiment with no commercial evidence beyond the author's own account.
User Stories BotA demo video on every pull request
Get a demo video on every new feature
GitHub App that watches your pull requests and records a narrated, captioned demo.
Save time on demo prep and make informed decisions faster with a video walkthrough of every new feature.
Source
Submitted to the OpenAI 2026 hackathon on Devpost. Project home on Devpost. Back to the full gallery on Devpost.
This competitive analysis was produced by top-founders.com (opens in a new tab)
Generated by a language model from this project's public Devpost page — its tagline, the author's own write-up and any built-with tags listed there — as captured in August 2026. Short quotations are the author's words. It is an opinion on the idea as a business, not on the people behind it, and it reflects the description as published then. If the project has moved on, request a correction below. The analysis is not independent research and contains no verified traction, revenue or customer data.
An independent guide by KFG International LLC — not affiliated with, endorsed by, or connected to Devpost or OpenAI.